
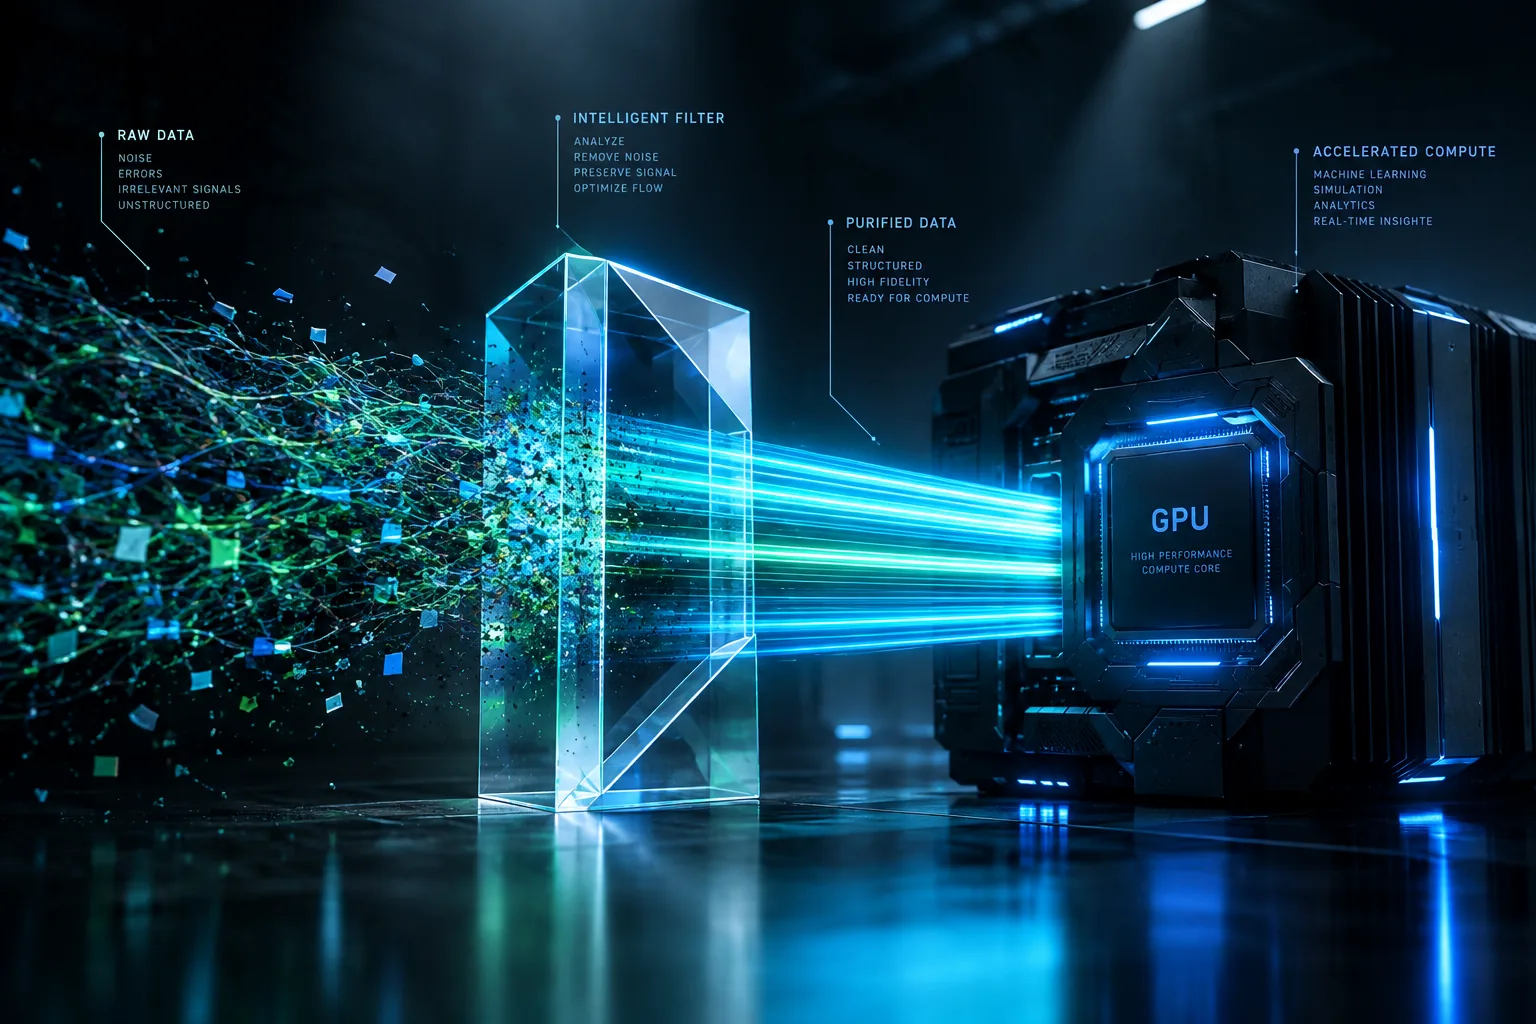
The Efficiency Dilemma of AI: Why Smart Pipelines Must Stop Thinking Overhead
The debate surrounding artificial intelligence revolves almost exclusively around model sizes, quantization levels, and benchmark tables. Whether on the local workstation or in large data centers: the primary goal is usually to achieve more parameters with the lowest possible latency.
However, the biggest operational bottleneck in modern language models often remains in the shadows: uncontrolled inference overhead.
Since modern architectures are increasingly trained on pronounced reasoning processes (Chain-of-Thought, often within internal <think> blocks), they spend significant computational time on internal self-talk. While this provides added value in highly complex logic puzzles or mathematical proofs, it proves to be pure resource waste in automated processes—such as in content management systems, documentation generators, or interface pipelines.
A two-stage architectural concept demonstrates how a deterministic control layer placed before the model core paves the way for extremely fast, efficient, and stable systems.
The Problem: The Silent Resource Hog
Typical implementations forward requests to the inference engine without reflection:
- Unnecessary Chain-of-Thought (CoT): The model generates hundreds of tokens of internal monologue just to output a JSON block or a code function. Each of these tokens consumes computational capacity and doubles or triples the response time.
- Static Context Blockages: Either the context window is dimensioned too small by default (leading to abrupt truncations with longer code or text outputs) or it is permanently allocated to the maximum, unnecessarily binding and fragmenting VRAM.
- Lack of Prompt Hygiene: Background processes often send redundant prompts, artificially inflating the Time-to-First-Token (TTFT).
Instruct vs. Reasoning: Two Model Worlds, Two Levers
To empirically and scientifically evaluate the effect of smart pipelines, a fundamental distinction between model architectures is indispensable:
1. Pure Instruct Models (e.g., Gemma, Llama-Instruct, Mistral)
Pure Instruct models possess no internal <think> loops. They naturally generate only the direct answer:
- Token Reduction: No thought tokens can be saved here. For an identical prompt, the pure token difference is exactly 0 percent, as the model inherently carries no thought overhead.
- The Real Lever: For such models, the preceding control layer primarily acts as a Hardware and Stability Guardian. It calculates the exact context requirement (n_{ctx), prevents Out-of-Memory crashes during long generations, and guarantees absolute bit-perfect reproducibility under T = 0.0 (100% Determinism).
2. Reasoning Models (e.g., DeepSeek-R1, QwQ, Qwythos-Mythos)
Models with inherent Chain-of-Thought generate a massive surplus of preliminary considerations by default, even when only a short translation, formatting, or data transformation is requested:
- Token Reduction: This is where the pipeline unleashes its full potential: Through targeted directive injection and post-filtering, 40 to 60 percent of the tokens are eliminated.
- The Real Lever: Execution time drops massively, power consumption decreases proportionally, and the KV cache in the GPU memory remains free for parallel batch requests.
The Two-Stage Pipeline: Concept & Architecture
Instead of letting every request run unfiltered into the inference engine, this architecture strictly separates the tasks: Rule-based preprocessing on the CPU, pure payload generation on the GPU or accelerator.
Architecture Workflow: Two-Stage Inference Pipeline
Detailed Functionality
- Directive Injection Pre-Inference: If the Engine detects a Reasoning Model or time-critical standard tasks, it injects strict instructions at the system level, suppressing the generation of thought tags. The model proceeds directly to the payload.
- Dynamic Context Scaling: If the Filter detects keywords indicating extensive outputs (e.g., complete code refactorings or long text segments), it calculates the anticipated token requirement in advance. The context window is then elevated to the next stable memory tier based on need, rather than blindly reserving memory or truncating mid-sentence.
- Post-Filter Safeguard: Should the Language Model still output minimal residual tags, the return logic intercepts these before the response reaches the requesting application.
Local Workstations vs. Global Cloud: Where is the Lever?
The principle yields enormous impact on both platforms, yet addresses different bottlenecks:
1. On the Local Workstation (e.g., Developer PC / Studio)
- VRAM Protection: Local GPUs have fixed memory limits. A dynamic filter prevents unnecessarily large context windows from being allocated or memory from being blocked by fragmentation.
- Temperature & Power Consumption: The hardware immediately downclocks after the actual generation, instead of calculating for seconds on discarded thought processes.
- Reliability: Longer outputs no longer break mid-sentence because the filter automatically reserves the necessary token buffer for the context window in advance.
2. In Large Cloud Clusters & Data Centers
- KV Cache Relief: In server farms, High-Bandwidth Memory (HBM) is the most expensive bottleneck. When millions of parallel queries "think" for hundreds of tokens, the internal KV cache clogs the entire cluster. Saving these tokens multiplies the overall throughput.
- Dramatic Cost Reduction: Eliminating superfluous tokens reduces operating costs for reasoning models by up to 40–60%, whether billed per token via API or based on pure hosting costs.
- Reduced Latency: Systems respond immediately without perceptible internal deliberation time.
Opportunities and Risks of the Concept
| Dimension | Architectural Advantages | Potential Disadvantages & Limitations |
|---|---|---|
| Speed | Immediate output in Reasoning Models; elimination of 40–60% waiting time. | No latency reduction in pure Instruct Models due to CoT blocking (as no CoT exists). |
| Resources | Lower GPU utilization, reduced VRAM requirement, measurable power savings (Joules). | Minimal CPU overhead for the heuristic (in the microsecond range). |
| Stability | Dynamic token reservations prevent context crashes during long responses. | Incorrect heuristics could potentially underestimate buffers in individual cases. |
| Content Depth | Precise, deterministic results for standard tasks, CMS, and code. | Quality loss in true Reasoning: Complex logic and mathematical proof problems require thought tokens for self-correction. |
Conclusion: The Future Belongs to Hybrid Systems
Pure neural networks are excellent generators but poor resource managers. Leaving the entire process and memory management to them is inefficient.
By placing deterministic, classically programmed filters ahead of the stochastic model engine, unnecessary overhead is removed from the overall system. Classical code handles what it does best (rules, memory calculation, structuring), while the language model is left with precise formulation.
This symbiosis is the key to operating local and global AI pipelines economically, responsively, and stably.