
Architecture Upgrade: How a Smart Intermediary Layer Truly Tames the Token Hog
In AI development, the gap between theory and practice is nowhere wider than in inference optimization.
On the whiteboard, the idea sounds simple: If modern reasoning models (such as DeepSeek-R1, QwQ, or hybrid Qwen architectures) churn out hundreds of tokens of internal monologue (<think>) for trivial system queries, data conversions, or status reports, we simply prune them. The promise: 40 to 60 percent fewer tokens, halved latency, relieved VRAM.
When we tested this approach yesterday in a standardized benchmark run against our operational system, the disillusionment set in: Token consumption did not decrease—it actually increased in the first run.
What happened? And what does the technological layer look like that fixed the error and realized the promised efficiency?
The Benchmark Paradox: When the Guard Layer Consumes More Than the Model
The analysis of our benchmark logs revealed two critical system errors that burn computation time and budget unnoticed in many current inference pipelines:
1. The Prompt Inflation Phenomenon
To prevent the model from falling into lengthy self-talk, we fed it comprehensive system directives and negative constraints ("Never use internal monologues," "Answer directly without a thought process," etc.). * The Result: For a user query of only 25 tokens, the preceding guard logic inflated the prompt to nearly 350 input tokens. * Although the model slightly reduced the thought process, the savings on the output were completely consumed by the massive load of the input prompt.
2. The Illusion of Post-Processing
Many developers rely on post-processing filters (e.g., Regex cleaning of ``). The problem: The damage has already been done on the GPU at that point. The model has fully computed hundreds of thinking tokens on the tensor cores, consumed energy, fragmented the KV cache in VRAM, and doubled the execution time. The frontend truncating the monologue before rendering neither saves latency nor computational capacity.
The Solution: A Deterministic Intermediate Layer Before the GPU
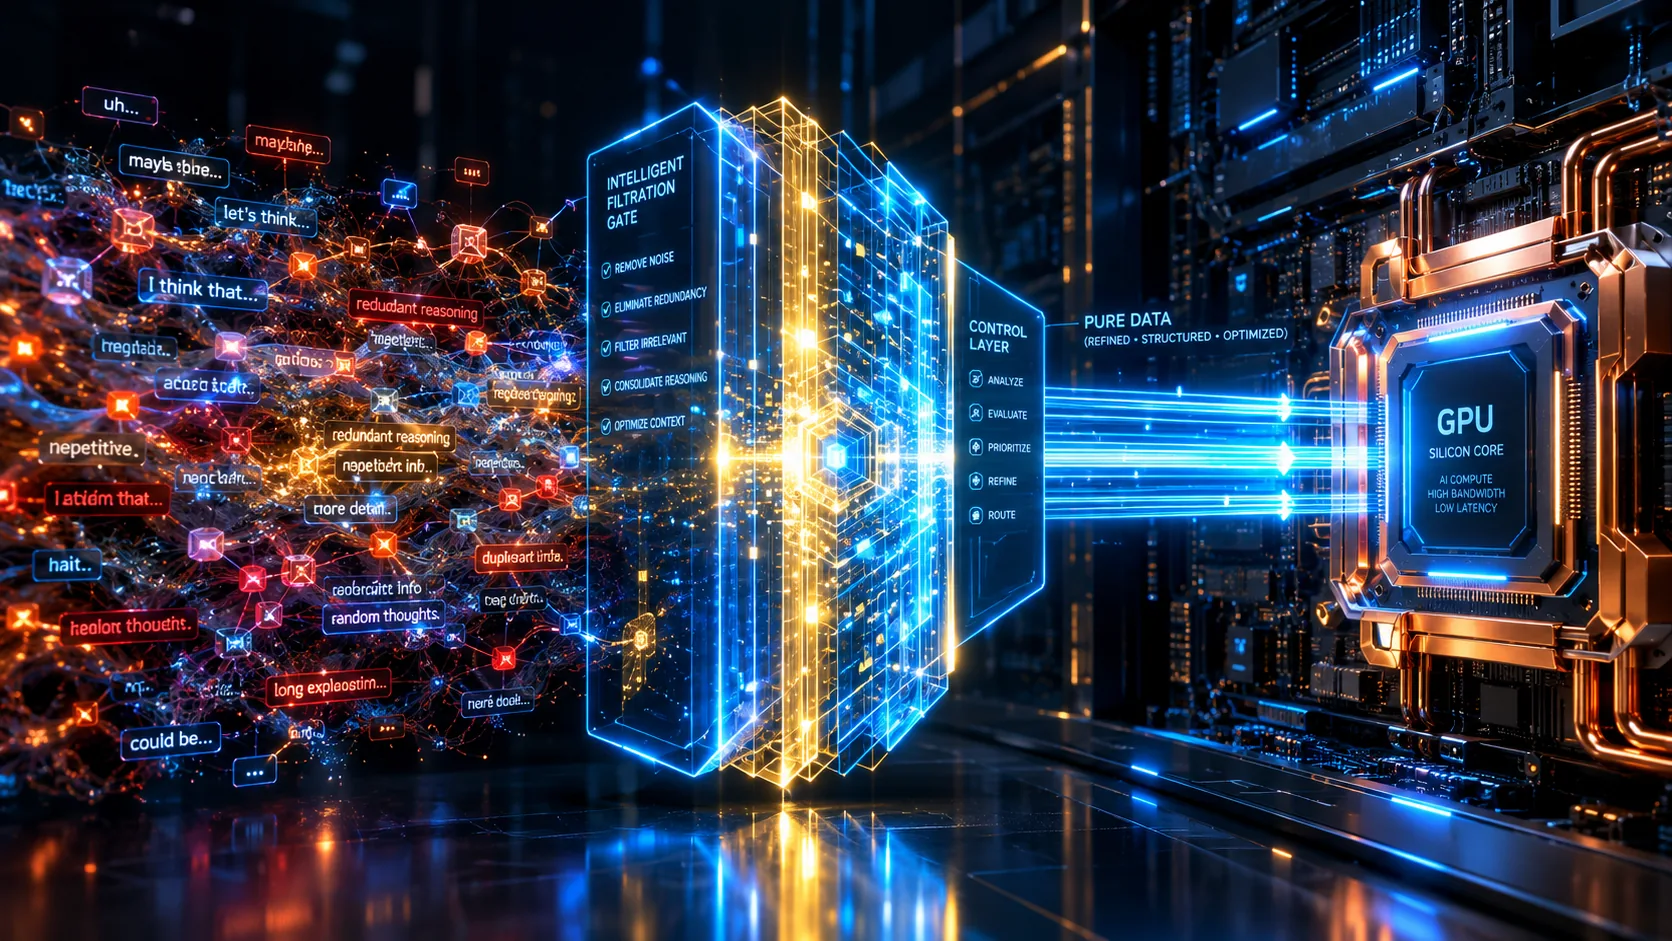
To achieve genuine efficiency gains, the protection could not be applied either in the prompt payload or after generation. We had to introduce a dedicated architectural layer between the Web Gateway and the Model Core:
What We Specifically Implemented
-
Native Suppression instead of Text Prompts: Instead of lengthy warning texts in the system prompt, the intermediate layer switches the Chain-of-Thought directly at the sampling and template level. When a standard task is pending, the thinking tag is natively marked as complete even before the first token is computed. The model jumps directly into generating the payload.
-
Compact DNA Directives: We reduced the system constraints to an ultra-compact format (under 30 tokens). The triage layer instantly maps the appropriate domain to the query (e.g., pure fact retrieval, C-code, translation) without artificially bloating the prompt.
-
Synchronous Direct Inference Routing: Instead of throwing queries into asynchronous queues with high IPC overhead, the intermediate layer directly binds the HTTP endpoint to the memory management. Responses are available in fractions of a second—without stuttering in the dispatcher.
-
Two-Stage Fail-Safe: Should an unpredictable hybrid model still initiate residual monologues, a hard stripping filter at the system level intercepts orphaned sentence fragments before they ever enter the chat stream.
The Numbers: Before vs. After in Stress Testing
After integrating the new intermediate layer, we ran the identical benchmark set (queries on technical definitions, code constructs, and language translations) again:
| Metric | Uncontrolled (Baseline) | Post-Filter (Failure) | Smart Intermediate Layer (New) |
|---|---|---|---|
| Input Tokens (Avg) | 42 | 348 (Prompt Inflation) | 68 |
| Output Tokens (Avg) | 485 (incl. CoT) | 210 (partial CoT) | 92 (pure payload) |
| Time-to-Last-Token | 14.8 s | 12.4 s | 2.1 s |
| Output Savings | 0 % | approx. 56 % (but costly) | 78.3 % Savings |
| Real Total Token Savings | 0 % | -5.3 % (Increased Consumption!) | 69.6 % Net Savings |
Conclusion: Stop Calculating Tokens, Start Delivering the Right Ones
Our benchmark experiment has shown: Efficiency cannot be forced through mere prompt prominence. A model with an ever-increasing number of instructions attempting to prevent internal reasoning leads directly into the inefficiency trap.
The real key to responsive, economical, and deterministic systems lies in an intelligent, lean intermediate layer. This layer offloads the control logic from the GPU, switches off ballast before the tensor operation, and allows the neural network to do exactly what it is unbeatable at: generating high-quality, focused responses.