
Neuro-symbolic Evolution: Why Local LLMs Should Not Be Knowledge Stores
Anyone running local Language Models on their own hardware knows the fundamental dilemma of modern AI pipelines: either you feed the system massive vector databases (classic RAG), which consume bandwidth and increase latency—or you rely on the parametric weights of the neural network and constantly battle hallucinations, stochastic guessing, and probabilistic forgetting.
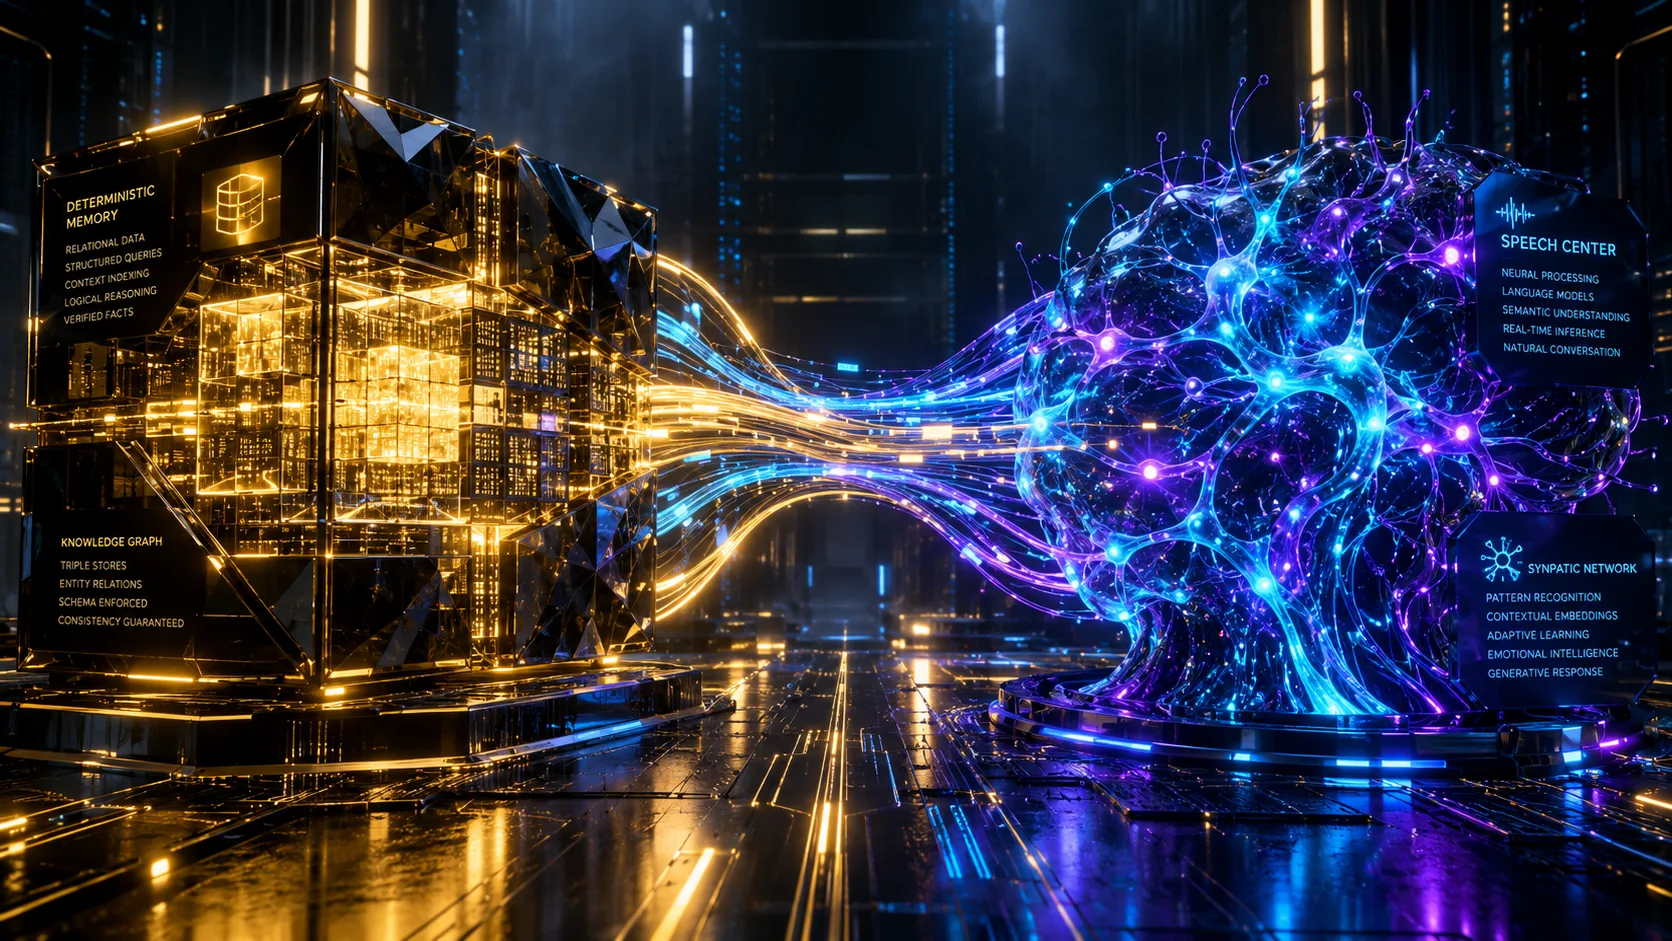
In the system architecture of L.U.N.A. Prime, we have broken this deadlock. The solution lies not in ever-larger parameter counts, but in a strict biological separation of functions: The relational database is the immutable long-term memory—the local LLM is the dynamic language center.
The Problem: The Overloaded Language Model
Classic chatbot and agent pipelines burden a language model with three fundamental tasks simultaneously:
- Fact Retrieval: What does the system know about Entity X? (probabilistically fished from billions of weights).
- Logical Deduction: In what ontological relation does X stand to Y? (stochastically interpolated at runtime).
- Language Synthesis & Formatting: How should this result be structured, eloquently, and syntactically flawlessly articulated?
The result on local hardware: High inference times of 15 to 20 seconds, noticeable latency, and responses that semantically drift with every follow-up question or fall into inappropriate recursion loops upon cache hits.
The Paradigm Shift: Neuro-symbolic Coupling
Our approach deterministically separates cognition and storage. A relational SQLite kernel operating in WAL mode assumes the role of the hippocampus, while the local inference dispatcher acts purely as the speech conduit (Broca's area).
The Core Components in Interaction
- Deterministic Ground Truth: Facts, taxonomies, and logical relations are stored symbolically and immutably in relational tables. They are retrieved deterministically from the database with sub-millisecond latency.
- Focused Speech Synthesis: The model does not have to guess facts. The verified relation is injected directly into the system context. Its computational power is 100% dedicated to what Transformers excel at: context understanding, sentence structure, eloquence, and structured Markdown output.
- Hardened Token Cache: Administrative confirmation phrases ("Instruction executed...") are actively excluded from the caching mechanism. Only substantive knowledge passes through the semantic cache, thereby preventing cache deadlocks with semantically inverted queries.
The Benchmark: Test Conditions & Methodology
To measure the performance of this coupling reproducibly, a three-stage evaluation procedure was set up for multidimensional concept hierarchies.
Test Environment & Framework
- Inference Node: Local system.
- Inference Engine: Local vGPU dispatcher with quantized GGUF models in VRAM.
- Memory Backend: Relational SQLite databases in WAL mode (
user_traits&facts). - Token Cache: 2-tier caching (SHA-256 + Token Signature) with strict exclusion of administrative status phrases.
The Three-Stage Test Scenario
- Stage 1 (Free Inference / Baseline): Querying a multidimensional concept definition without prior relational priming. The model must simultaneously and purely probabilistically calculate fact retrieval, logical demarcation, and synthesis.
- Stage 2 (Deterministic State Commit): Physical writing of the validated relation into the relational structure upon confirmation—without administrative confirmation texts corrupting the semantic token cache.
- Stage 3 (Relational Cascade & Inverse Query): Checking for logical consistency via semantically inverted prompts and introducing deeper subcategories (cascading across 3 abstraction levels: Superordinate Term \longrightarrow Functional Specialization \longrightarrow Structural Unit).
Measurement Results & System Behavior
| Test Phase | Architecture Path | Latency (Total) | GPU Load | Semantic Drift / Hallucination |
| :--- | :--- | :---: | :---: | :---: |
| **Free Inference (Baseline)** | Pure LLM (Stochastic Search) | **17.37 s** | 100 % (Full Pipeline) | Present (Definitions vary upon rephrasing) |
| **Guided Synthesis (Hybrid)** | SQLite Ground-Truth + LLM Speech Synthesis | **2.63 s – 4.55 s** | Low (Focus purely on articulation) | **0 %** (Deterministically bound to database fact) |
| **Cached Status Messages** | Token Cache Engine | **0.05 s** | 0 % GPU | Prevented: Administrative platitudes are actively blocked |
What These Results Mean in Practice
1. Drastic Latency Reduction (4 to 6 times faster)
Because the language model does not first have to deduce the hierarchical classification in the latent space, the computationally intensive stochastic search process is eliminated. The time to the first token and the total duration drop massively, as the model operates immediately as an articulating tool for verified data.
2. Cascading Term Growth
When a new subcategory is queried, the system automatically references the taxonomy already anchored in the database. The model organically builds upon the existing concept tree instead of stringing together isolated individual answers:
Supercategory (Construction) ──> Specialization (Function/Purpose) ──> Component Unit (Completed Space)
3. Robust Inversion Stability
If the query is linguistically inverted, this no longer results in an erroneous cache hit on old receipt entries, but rather in a new, contextually adapted formulation based on the identical factual foundation.
Conclusion
True system reliability is not achieved by blindly scaling model parameters, but by the symbiosis of deterministic memory architecture and neural linguistic competence.
L.U.N.A. Prime no longer operates purely stochastically in a vacuum: it draws upon an unshakeable relational knowledge foundation and utilizes its local model precisely for what Transformers were created for—for precise, vivid language.